
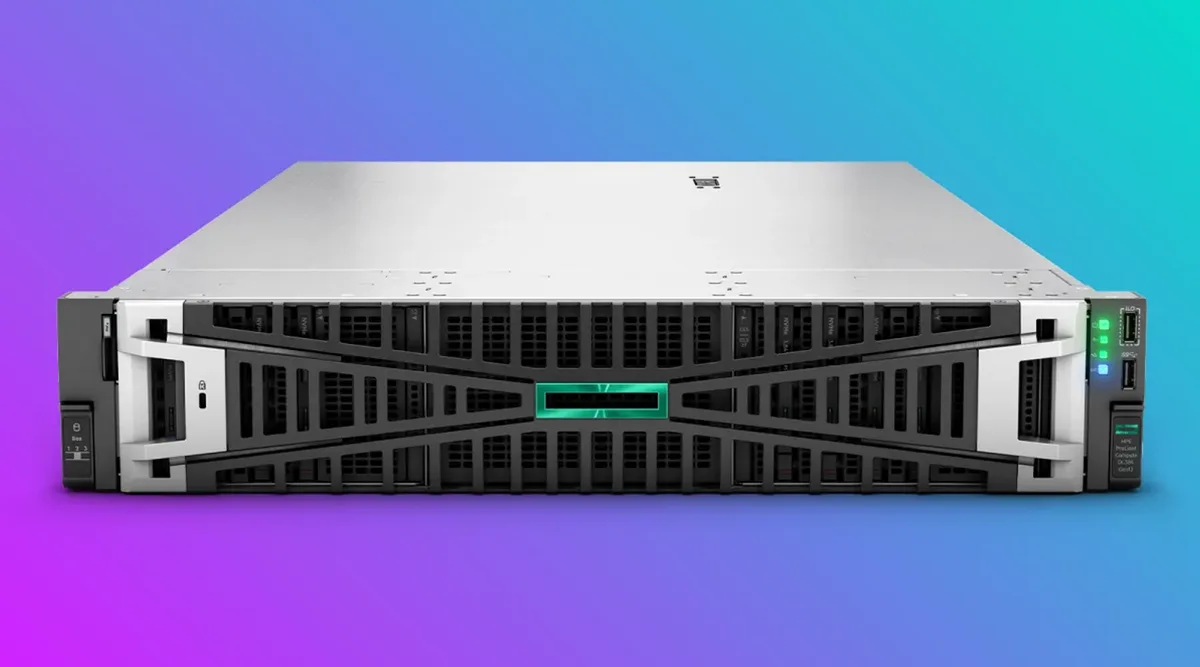
HPE
HPE ProLiant Compute DL384 Gen12 barebone server
Barebone server for generative AI workloads with NVIDIA GH200 NVL2 superchips
- Supports up to two NVIDIA GH200 NVL2 superchips per server
- Outstanding coherent memory and memory bandwidth for larger models
- Superchip performance delivers superb performance per GPU in HPE ProLiant portfolio
- Simplifies scaling with data demands for mixed workloads and RAG
HPE ProLiant DL384 Gen12 for AI
The HPE ProLiant Compute DL384 Gen12 is a barebone server built for accelerated computing. It supports up to two NVIDIA GH200 NVL2 superchips to run large generative AI models. Teams can scale out infrastructure for retrieval-augmented generation and mixed workloads in a hybrid environment. This platform targets organisations that need coherent memory and high bandwidth for AI factories.
Dual superchip configuration decides fit
The server holds up to two NVIDIA GH200 NVL2 superchips, which determines whether the density matches your model size. Buyers who need more than two superchips per node or who require a different GPU architecture should evaluate other platforms. The barebones design means you add the specific components your workload demands.
Highlights
- Supports up to two NVIDIA GH200 NVL2 superchips per server
- Outstanding coherent memory and memory bandwidth for larger models
- Superchip performance delivers superb performance per GPU in HPE ProLiant portfolio
- Simplifies scaling with data demands for mixed workloads and RAG
Specifications
No published specifications for this item yet.
Questions about this item
What does the 384 figure mean for model size once the server is deployed?
The 384 figure represents the maximum number of superchips the system can scale to, letting teams run larger models across the expanded coherent memory pool.
What interface standard connects the superchips and what does it cap in practice?
NVIDIA GH200 NVL2 links the superchips, capping the configuration at two per server while delivering the coherent memory bandwidth needed for generative AI workloads.
New to this? Buying server hardware with crypto — what to check, what it costs to pay, and what is never asked for.
Also in this aisle
People compared these
Same shelf, same checkout — eight coins and a 30-minute rate lock.


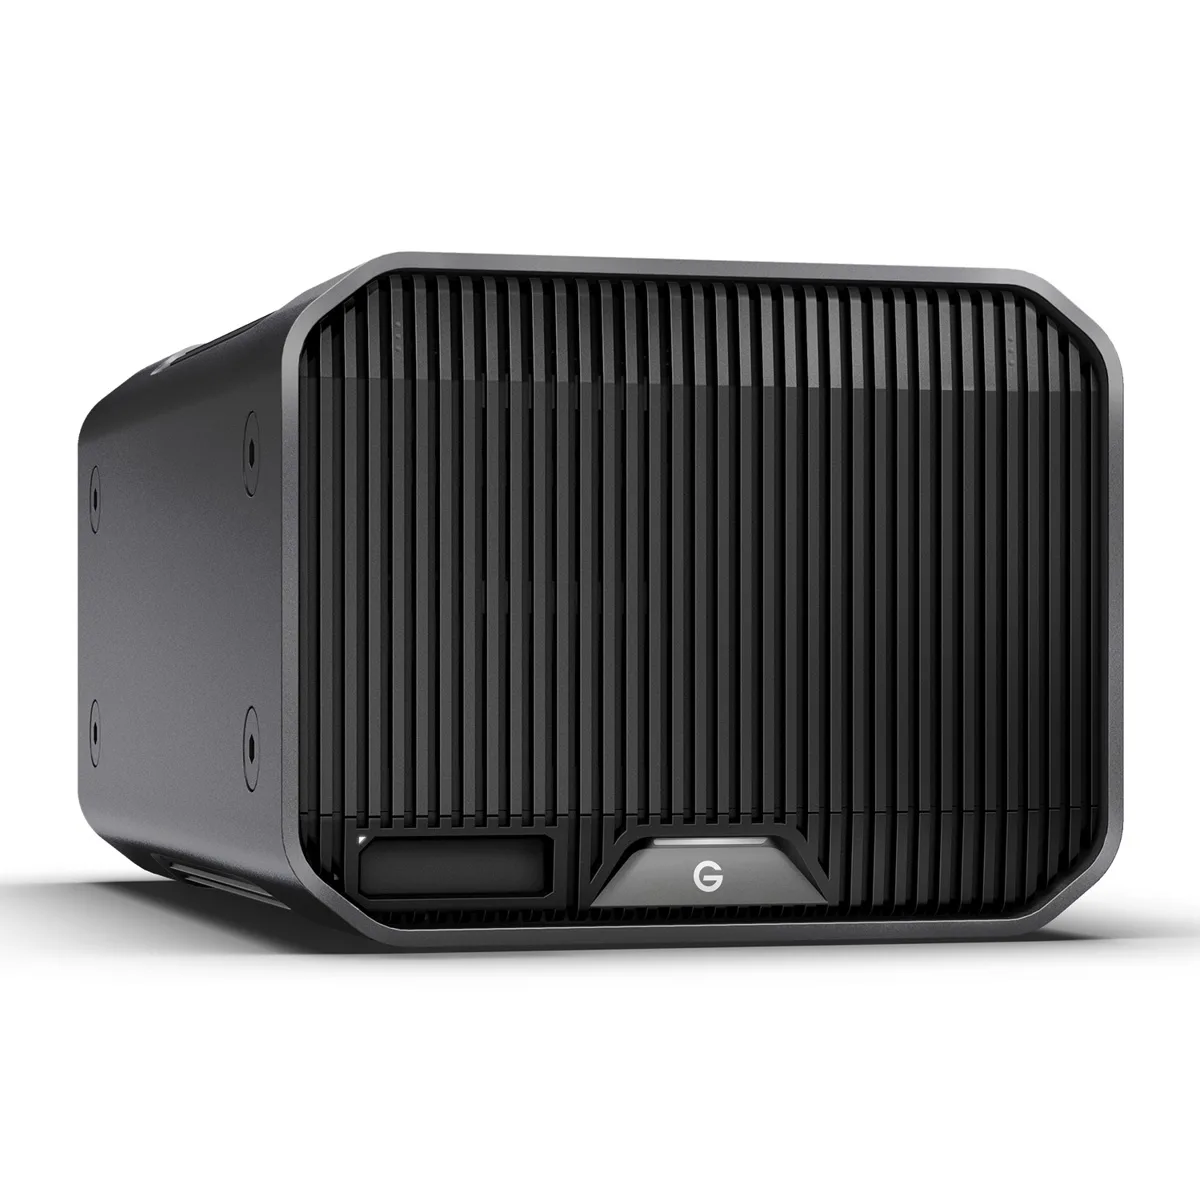
Western Digital
Western Digital SDPHK2H-024T-NBAAD 24TB G-RAID PROJECT 2 raid enclosure
$1,209.99
0.01397976BTC
In stock
OWC
OWC ThunderBlade X12 48TB RAID enclosure OWCTB5TBL12X048
- ThunderBlade X12 Ex…
$11,647.99
0.13457639BTC
In stock